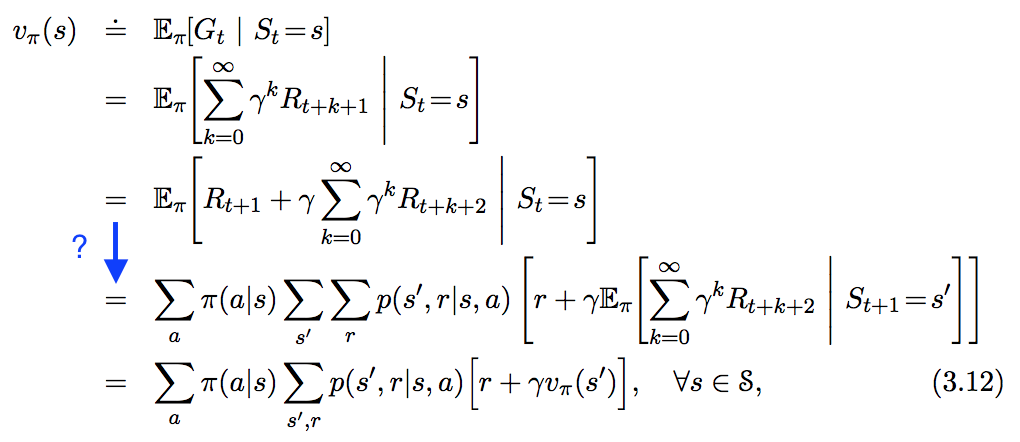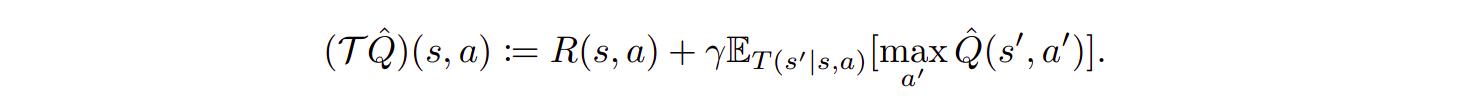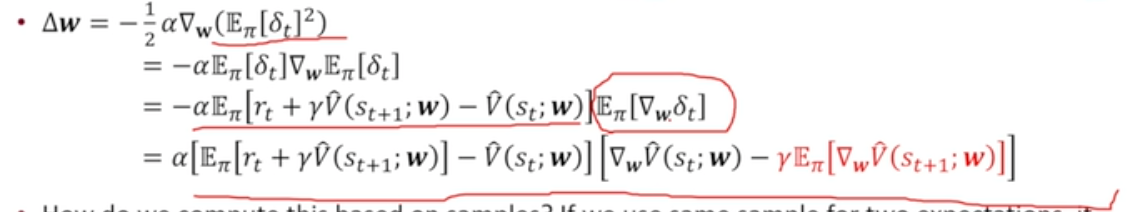Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
Generalizing the Projected Bellman Error Objective for Nonlinear Value ...
Bellman error corresponding to the estimates of h based on the three ...
Histogram of the maximal Bellman error when discount factor β = 0.8 and ...
Histogram of the maximal Bellman error when discount factor β = 0.99 ...
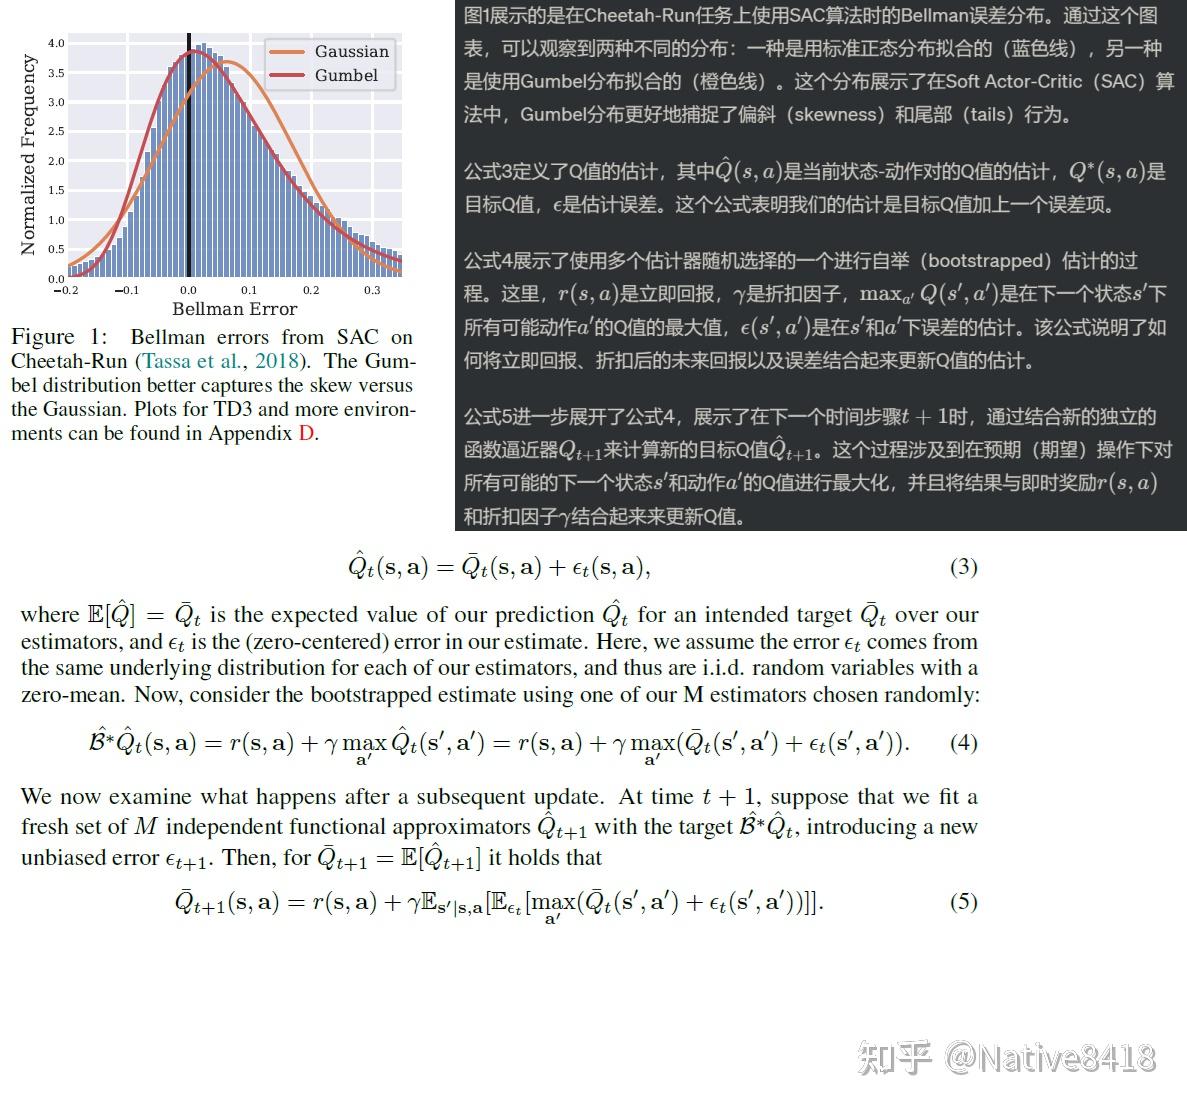
Figure 1 from Symmetric Q-learning: Reducing Skewness of Bellman Error ...
Does bias explain the non-correspondence between Bellman error and ...
Reward, Bellman error and βop estimate over episodes. We see that the ...
Squared Bellman error considered harmful: Loss functions plotted as a ...
Figure 4 from A Generalized Projected Bellman Error for Off-policy ...
Example of squared Bellman error (16) | Download Scientific Diagram
Consider the problem of estimating the Bellman error Q k − T * Q k 2 ν ...
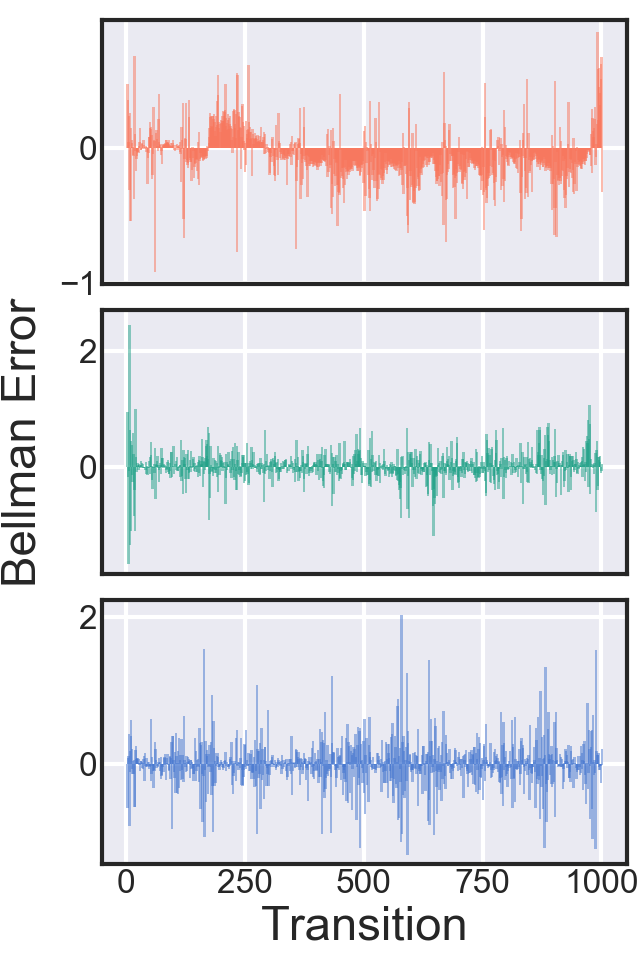
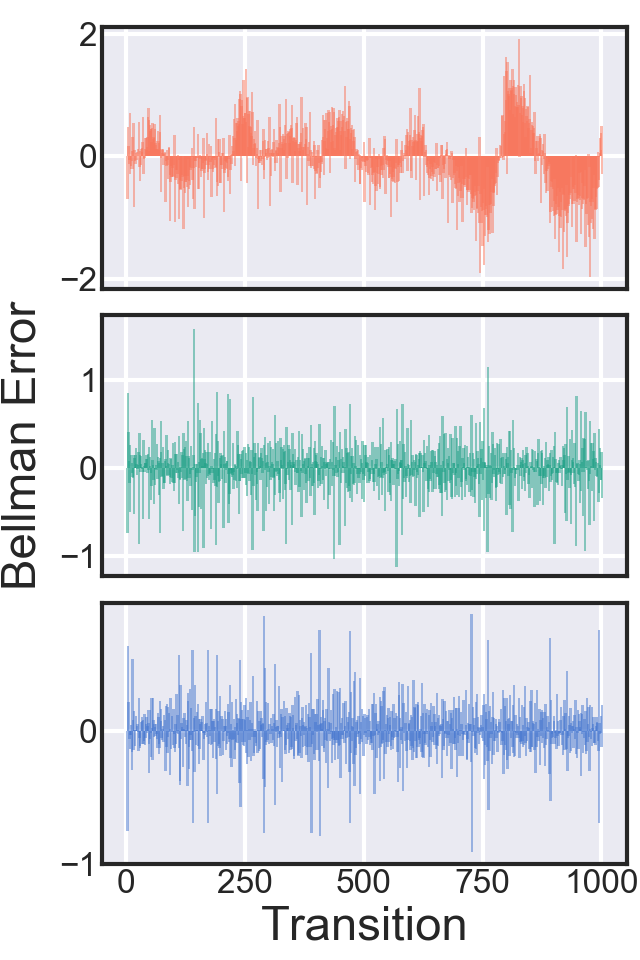
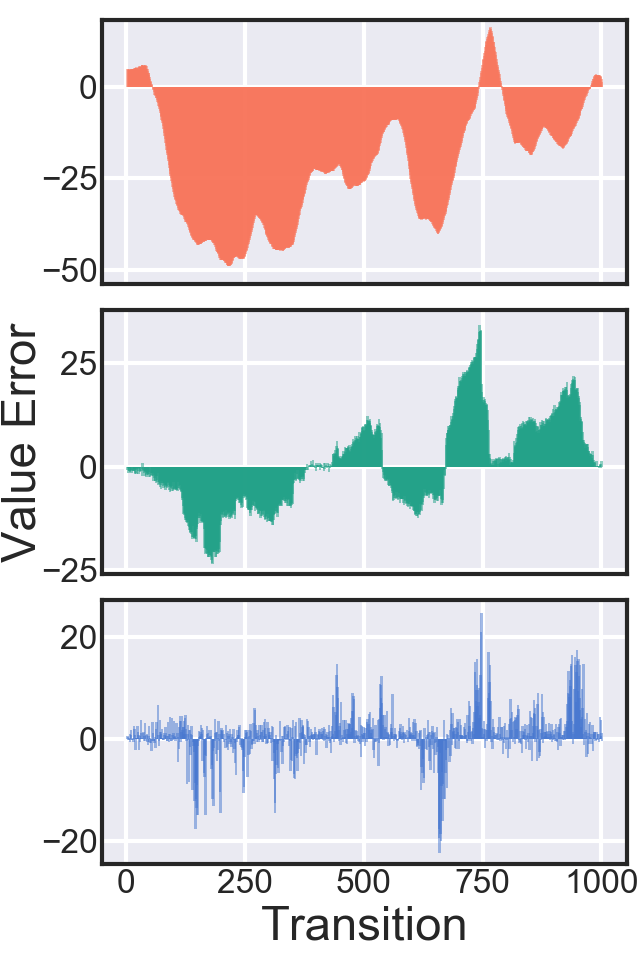
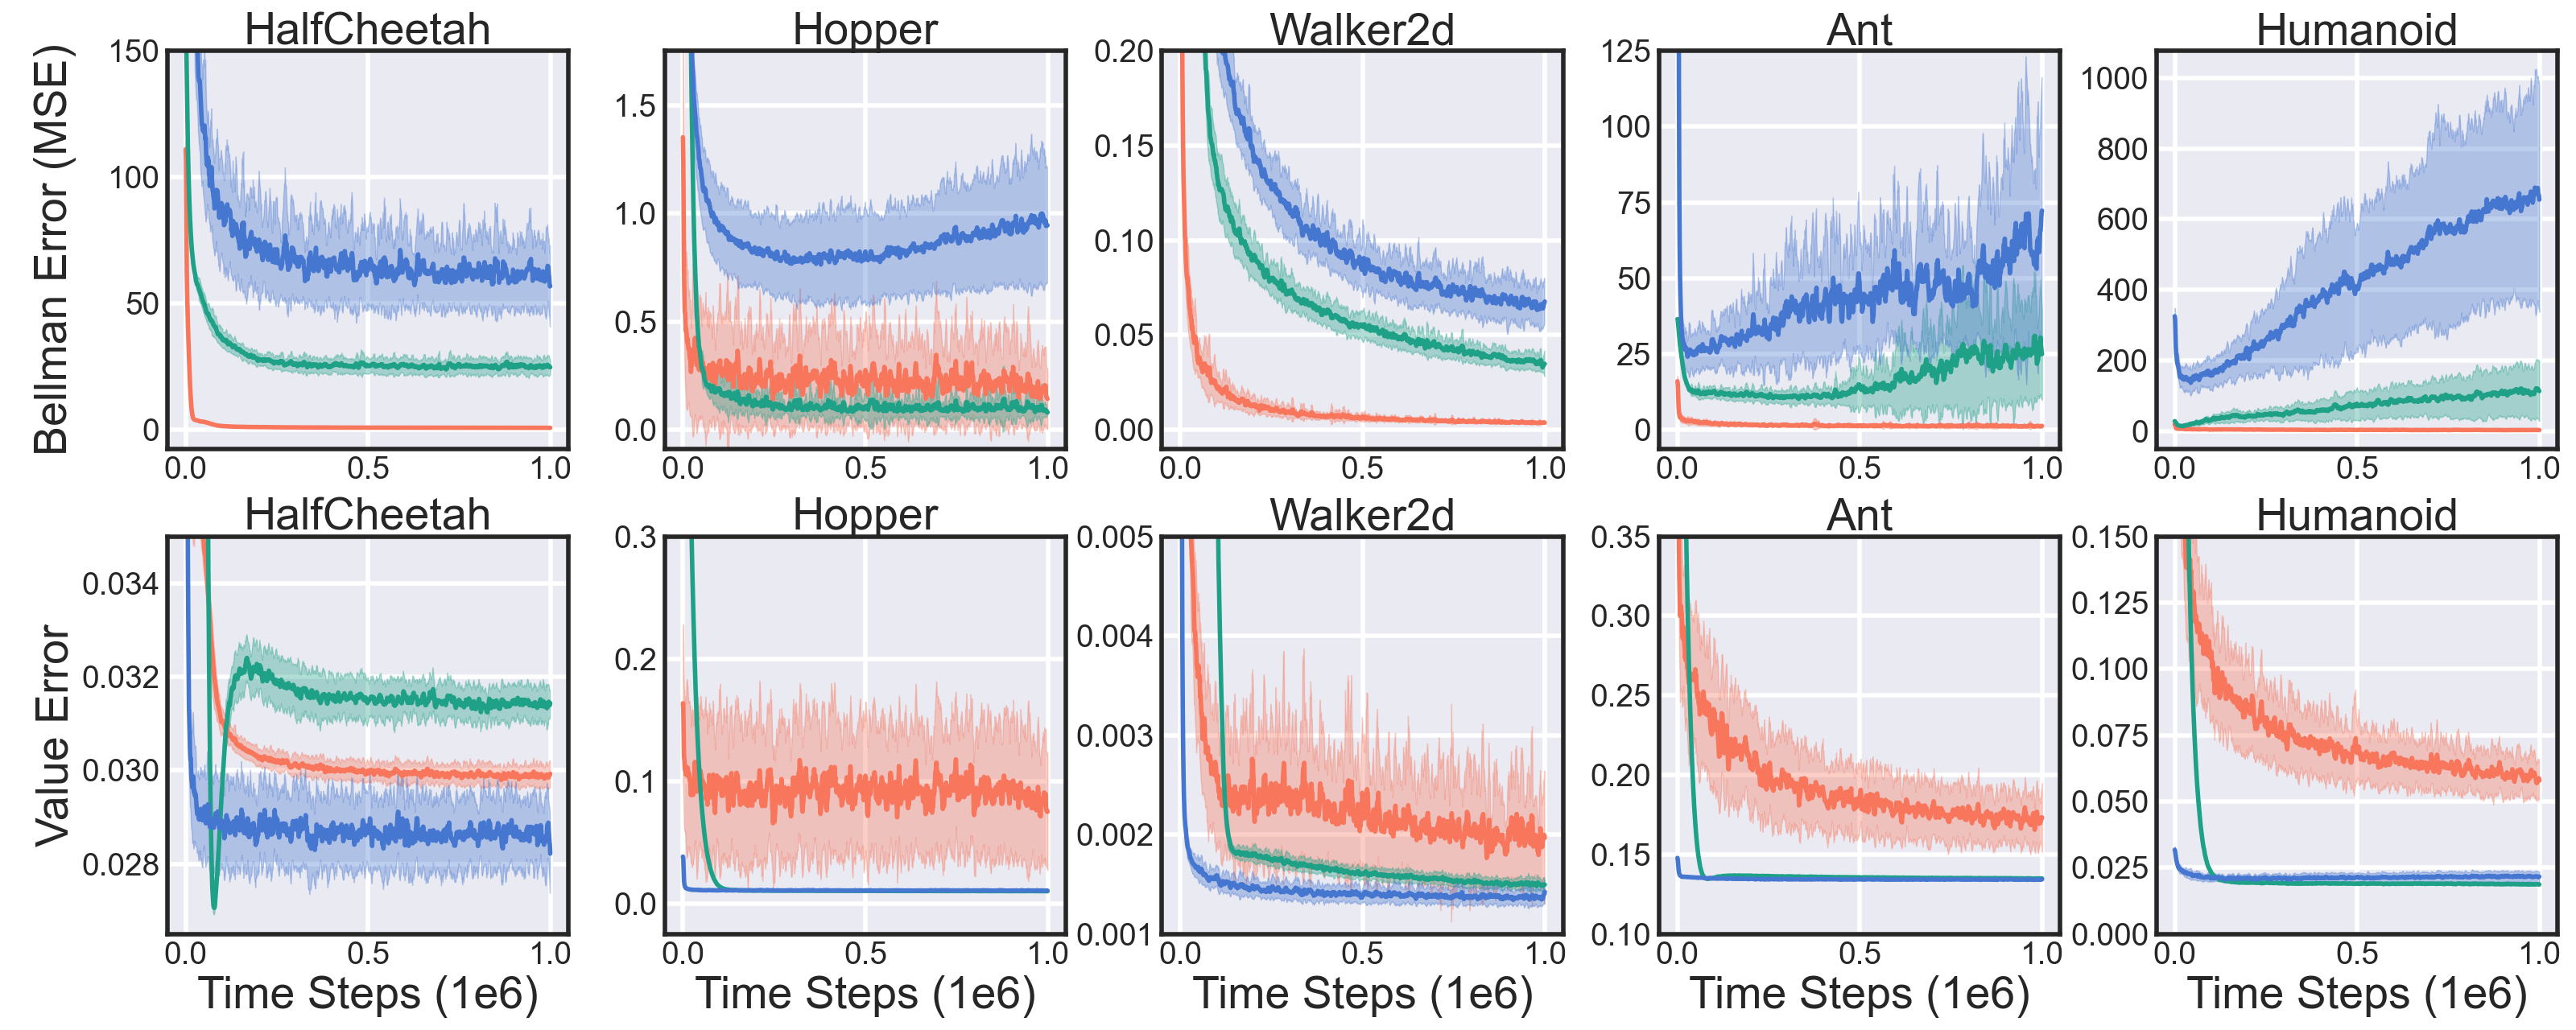
Figure 1 from Why Should I Trust You, Bellman? The Bellman Error is a ...
Bellman error corresponding to the estimates of h using LSTD and LSTD ...
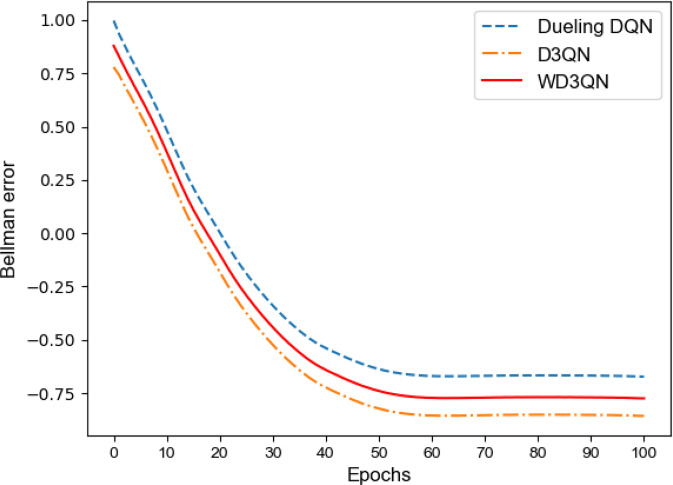
Bellman error resulting from application of different Q-learning ...
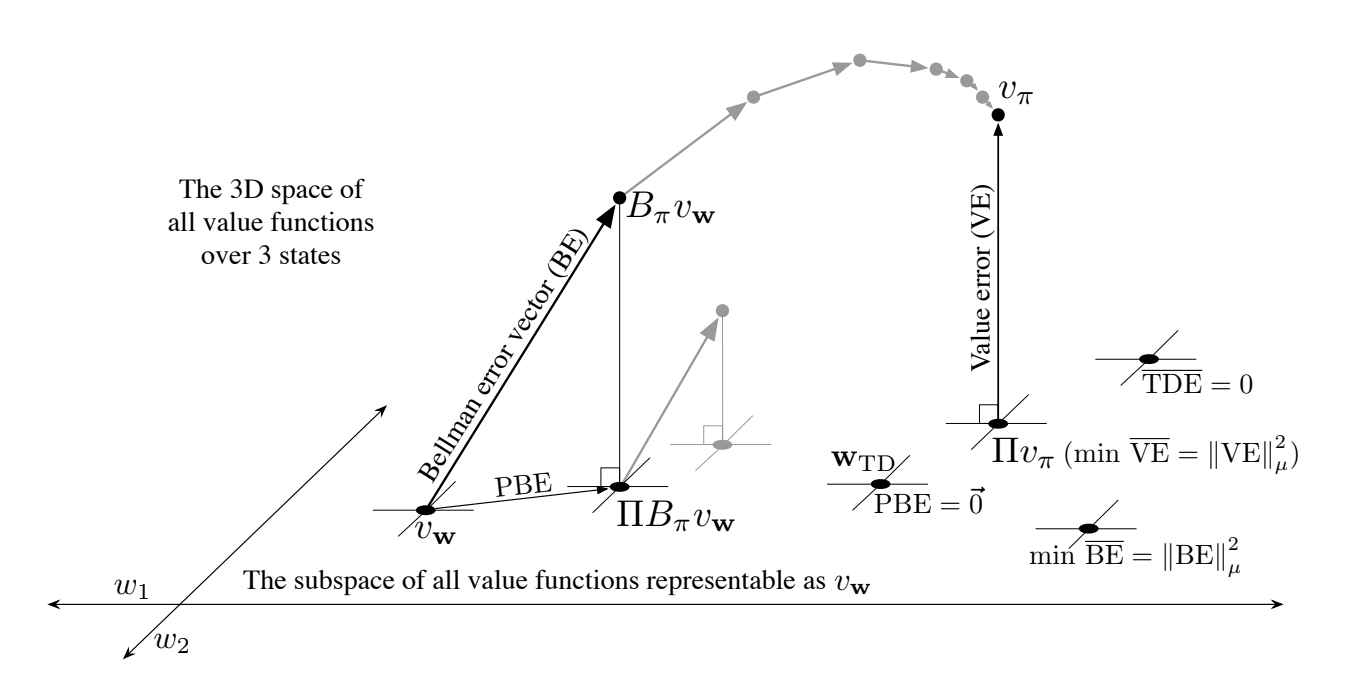
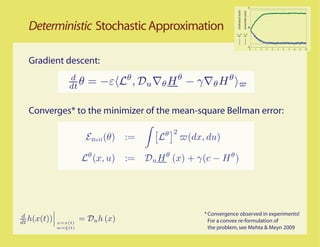
The geometrical relationship between the mean squared Bellman error and ...
Bellman Error (over 10 runs): Four outcomes. | Download Scientific Diagram
The Role of Inherent Bellman Error in Offline Reinforcement Learning ...
[2201.12417] Why Should I Trust You, Bellman? The Bellman Error is a ...
Figure 5 from A Generalized Projected Bellman Error for Off-policy ...
(PDF) Why Should I Trust You, Bellman? The Bellman Error is a Poor ...
Figure 1 from A Generalized Projected Bellman Error for Off-policy ...
Error and solution plots of the Bellman equation on a 2048 size grid ...
Summary of the Q-learning algorithm result: Average Bellman error ...
Bellman error for 2 resources, 5 tasks. | Download Scientific Diagram
Bellman residual error for the local quadratic approximation of the ...
Deterministic Exploration via Stationary Bellman Error Maximization
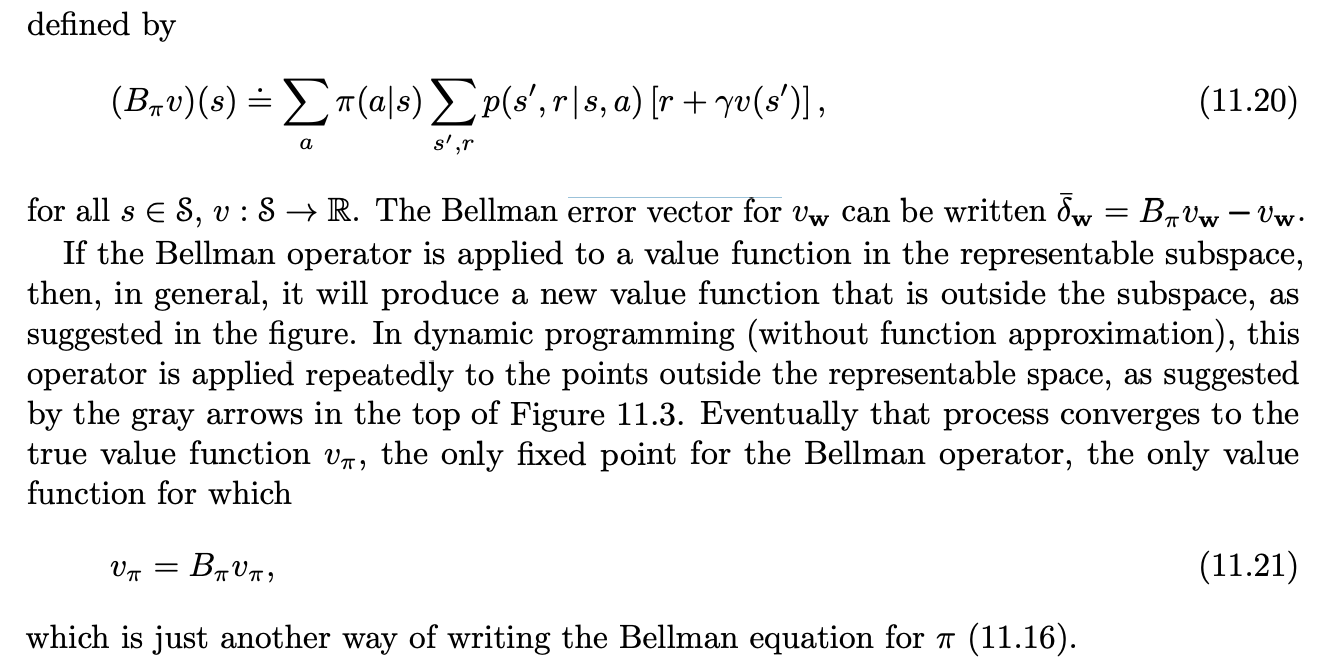
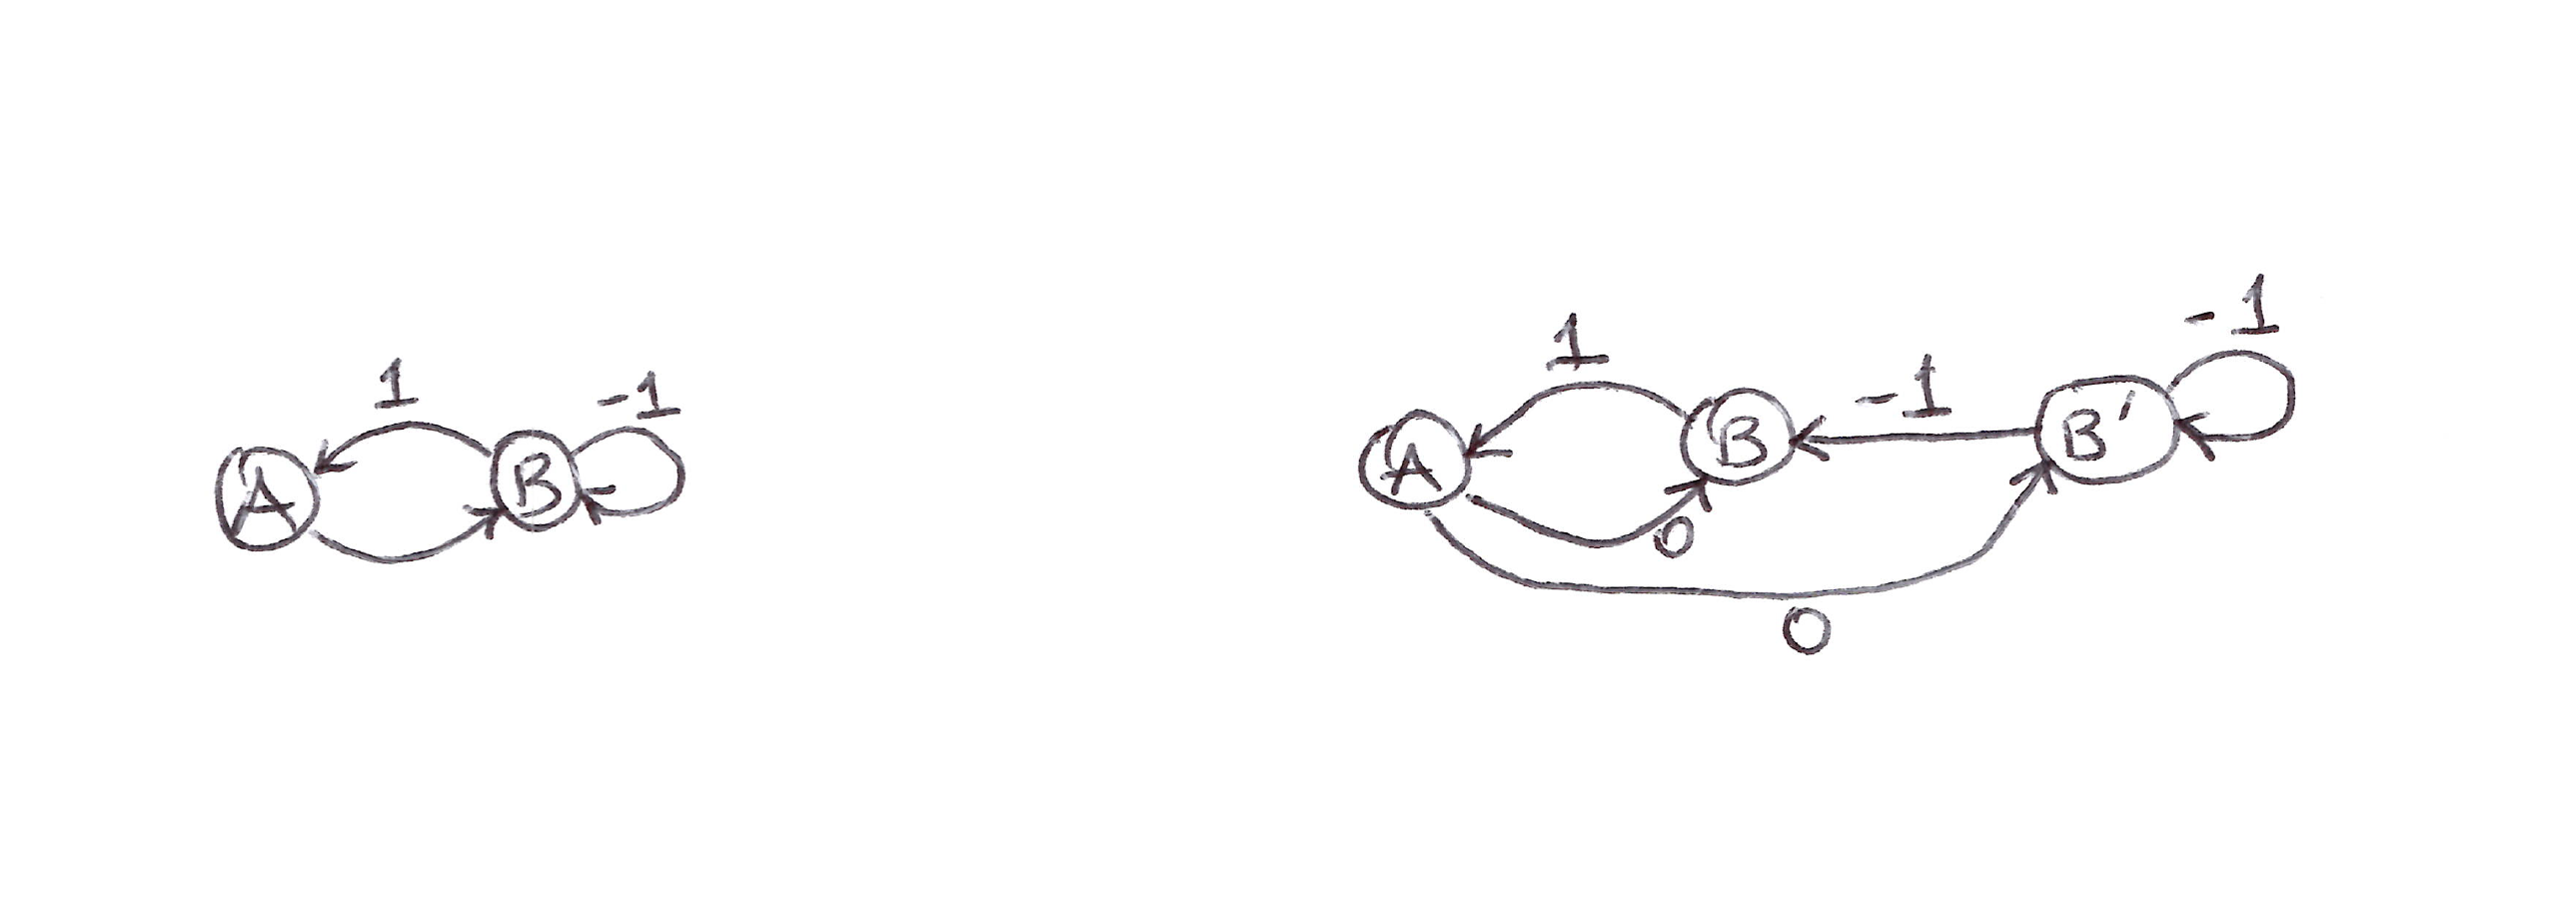
Sutton and Barto Reinforcement Learning Chapter 11: Bellman Error Flaws ...
Bellman Error Based Feature Generation using Random Projections on ...
Symmetric Q-learning: Reducing Skewness of Bellman Error in Online ...
(PDF) Método de error de Bellman con ponderación de volumen para ...
Convergence plot of modified Q-learning scheme: (a) shows the Bellman ...
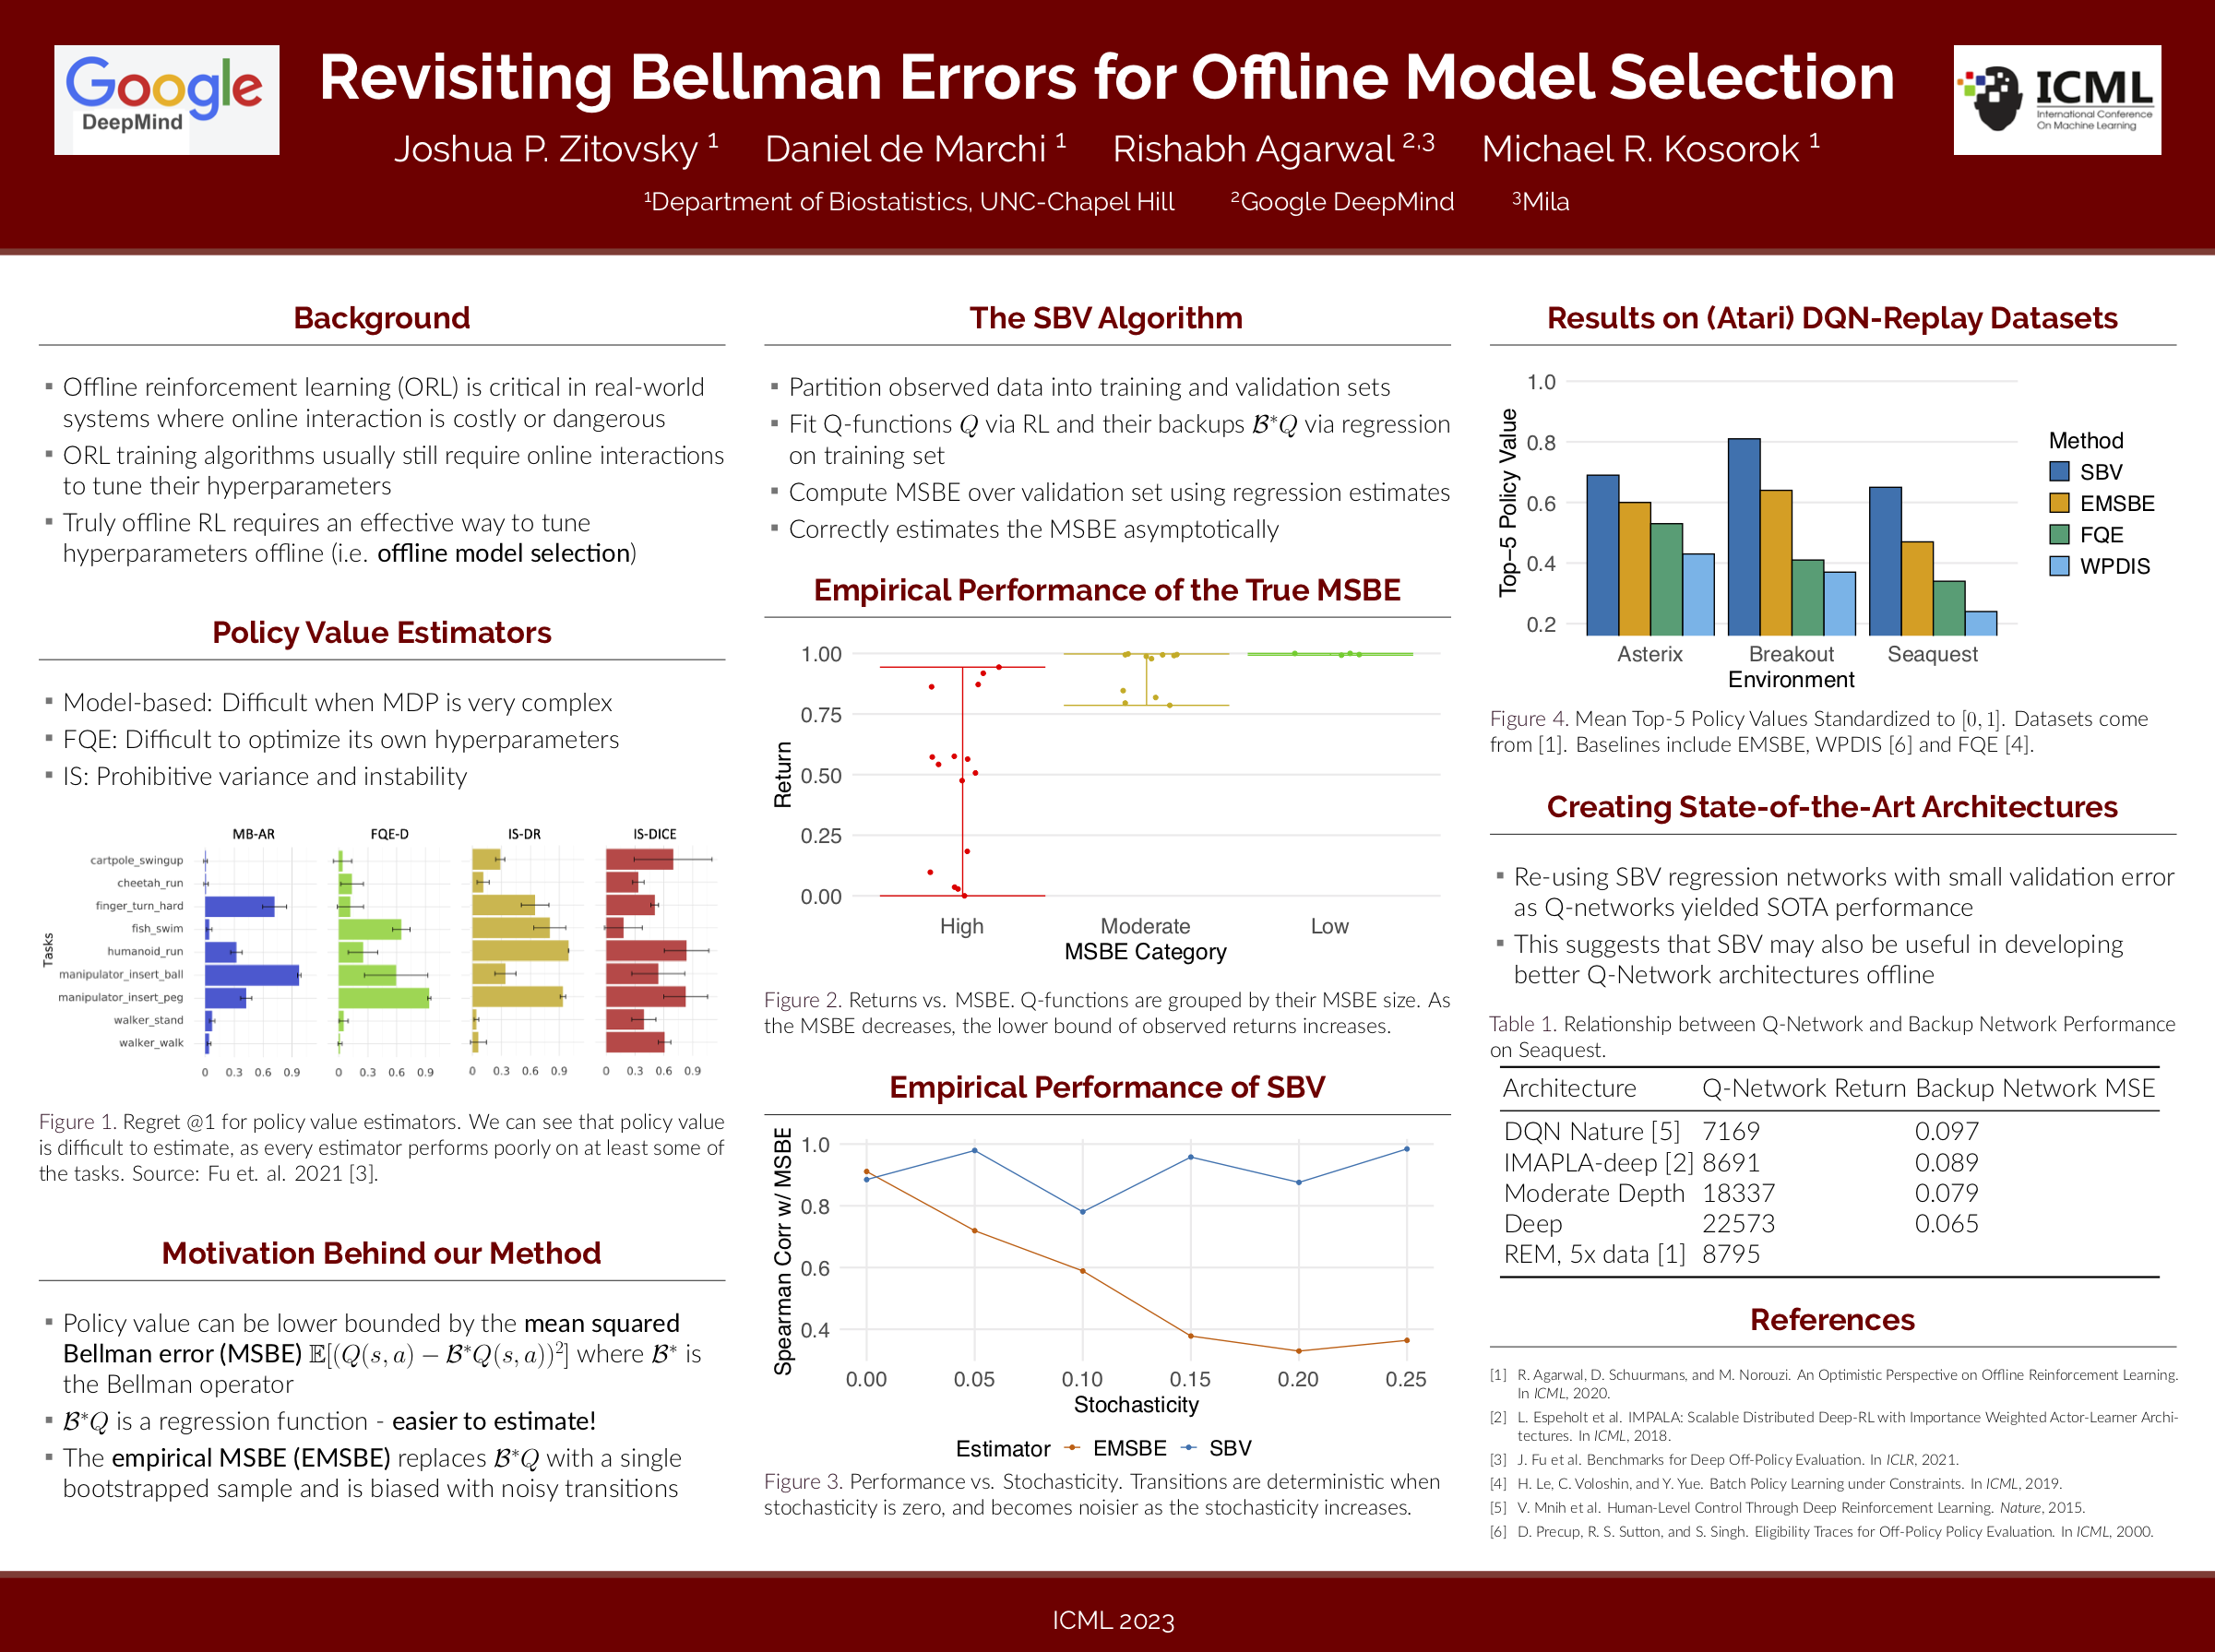
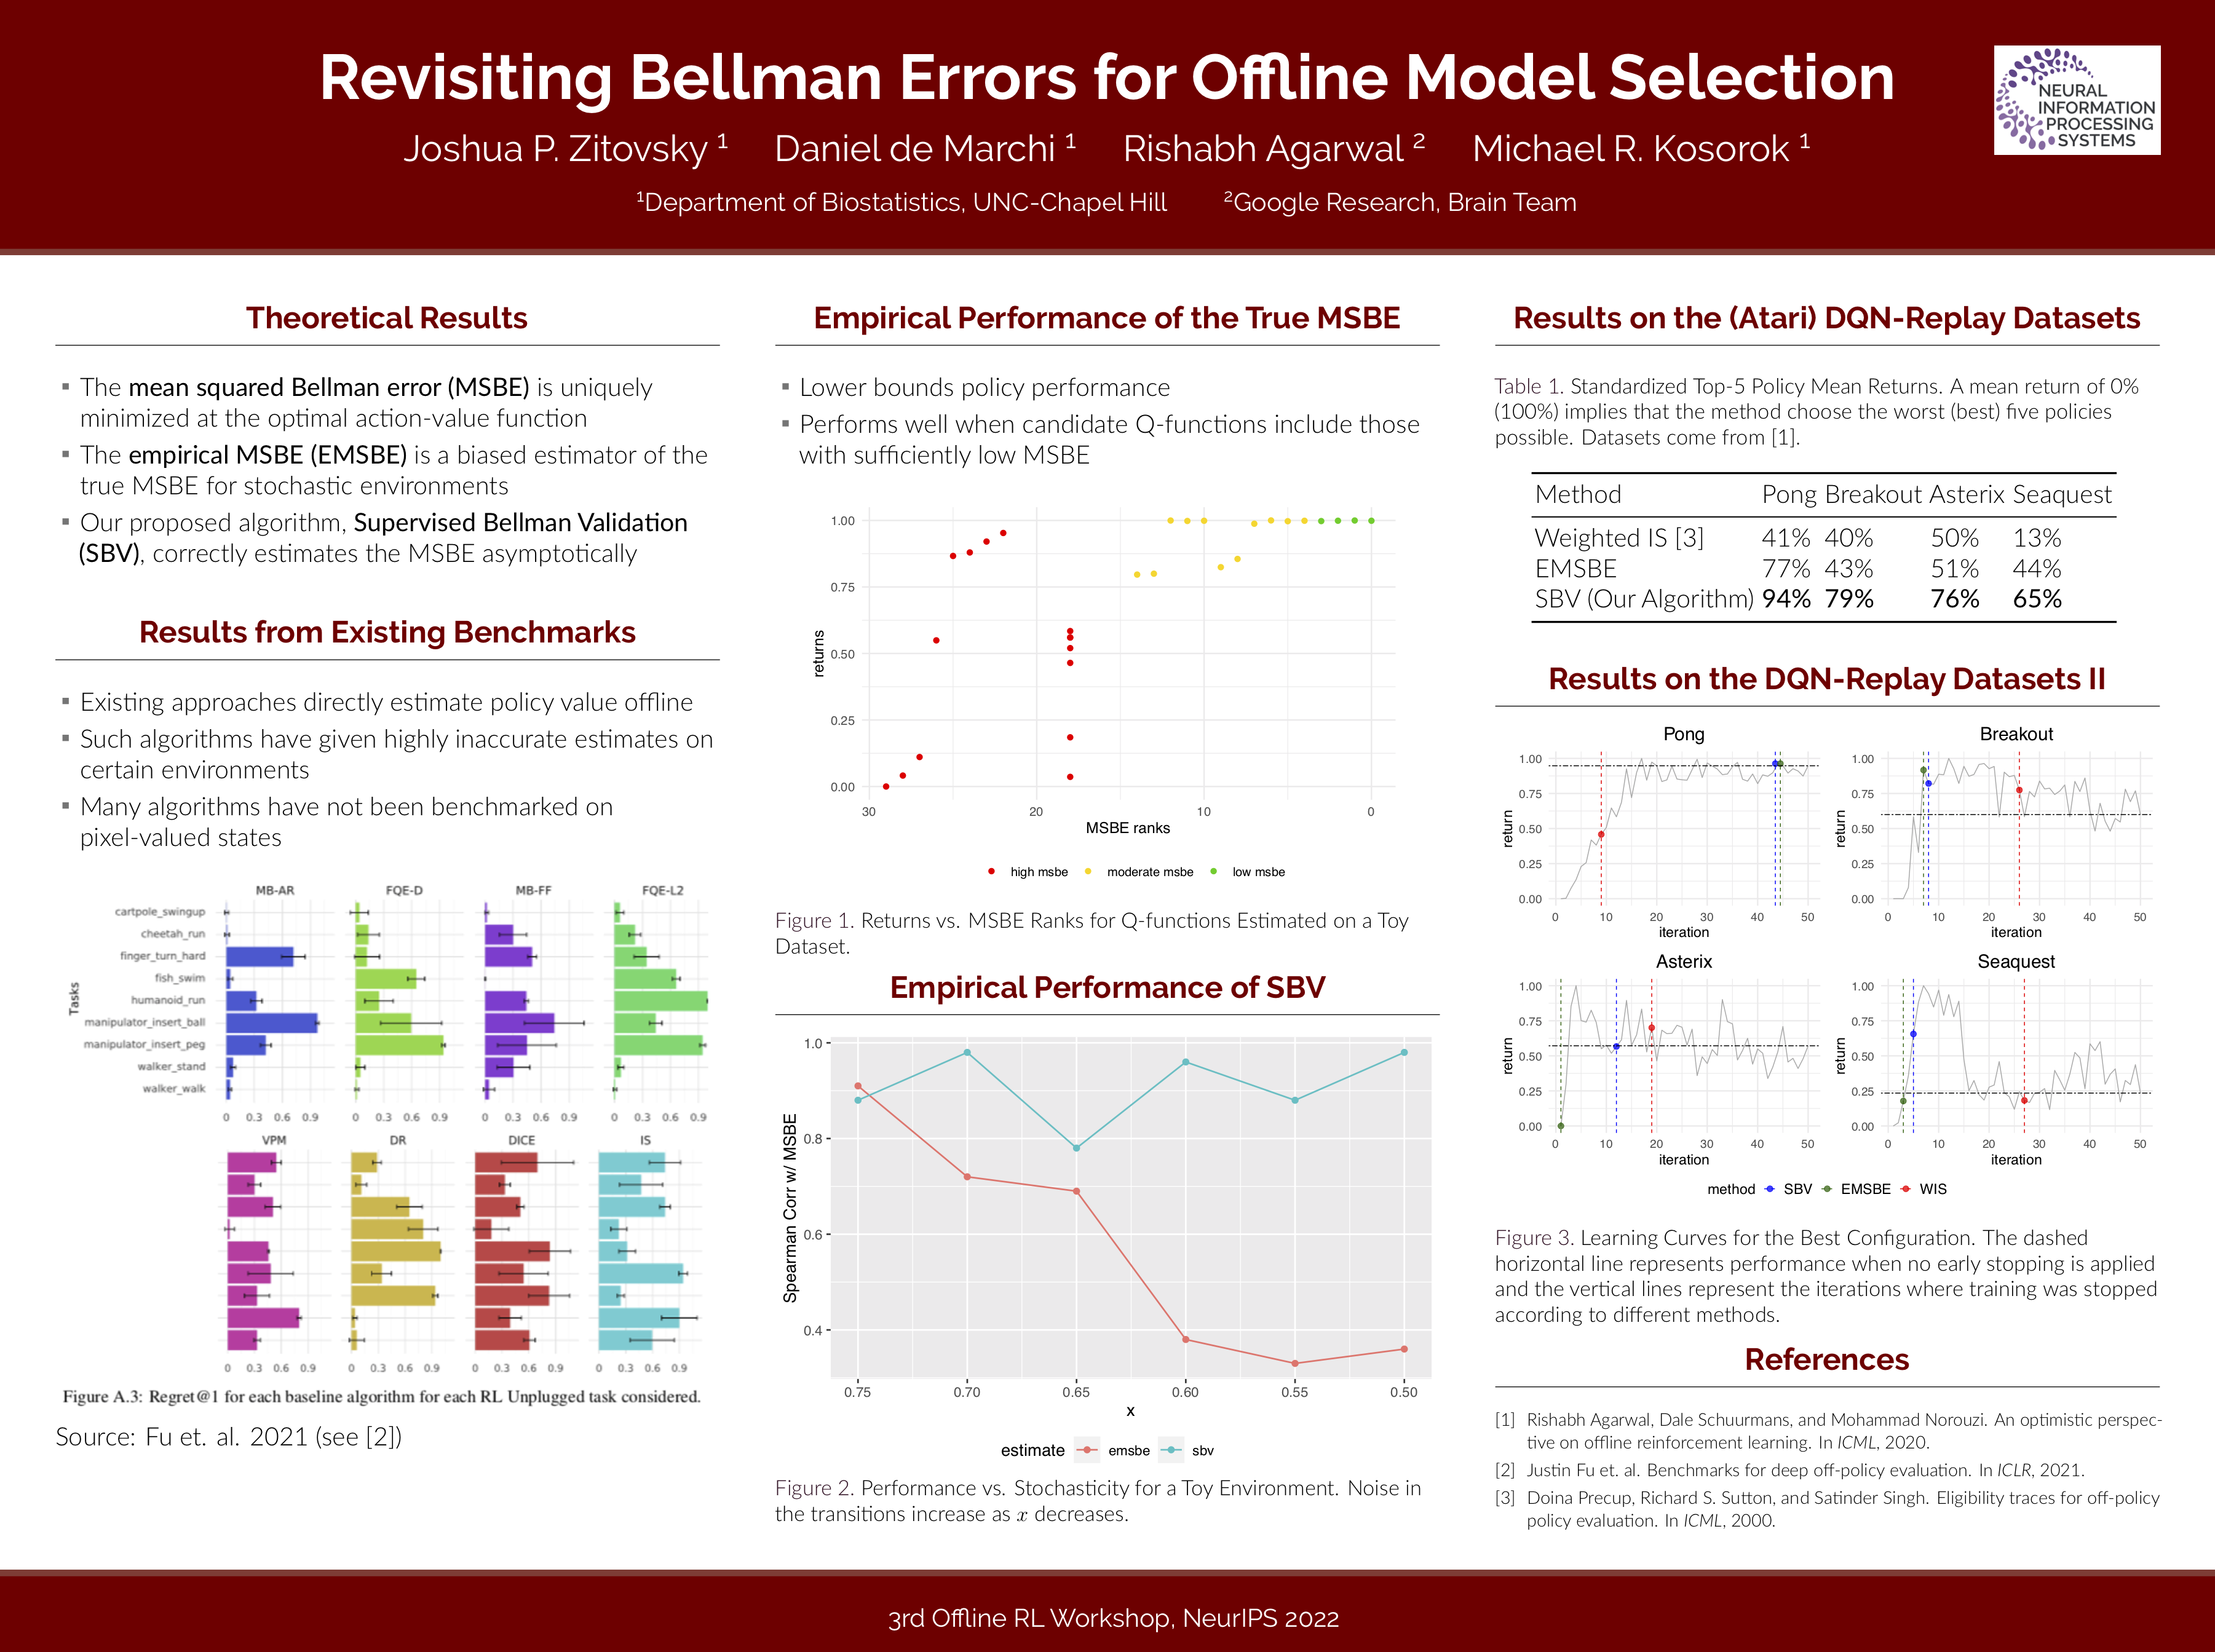
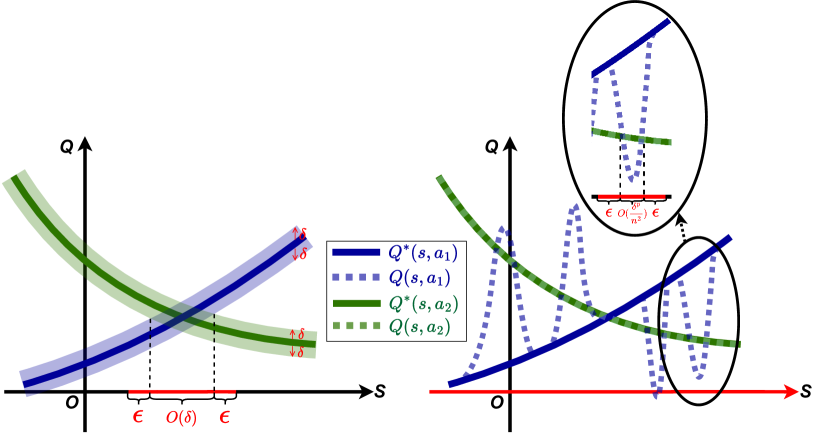
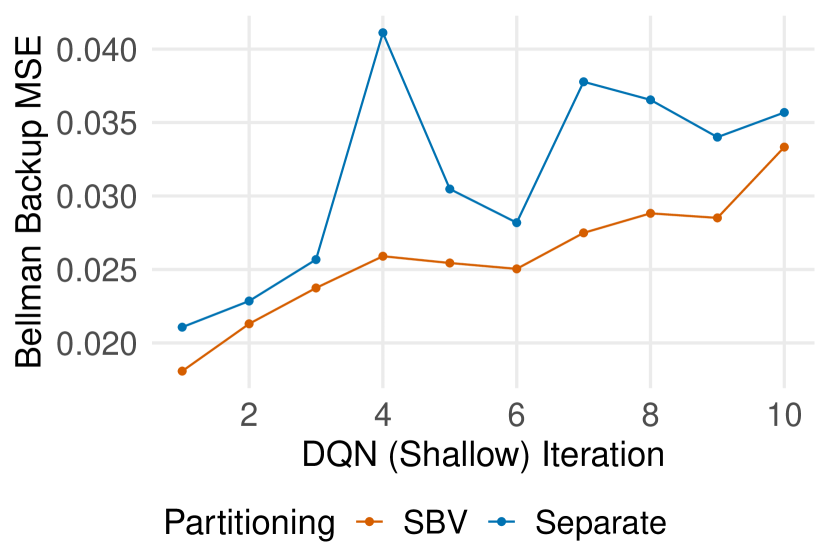
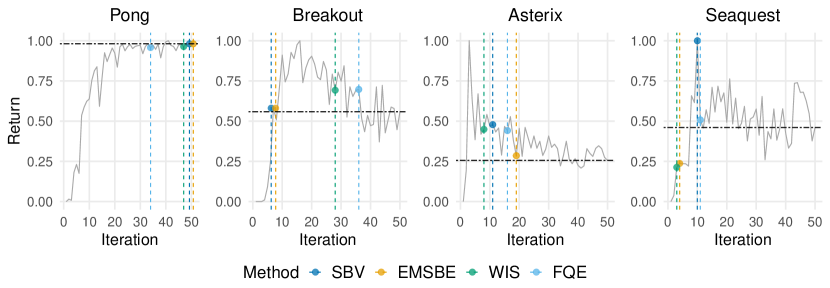
ICML Poster Revisiting Bellman Errors for Offline Model Selection
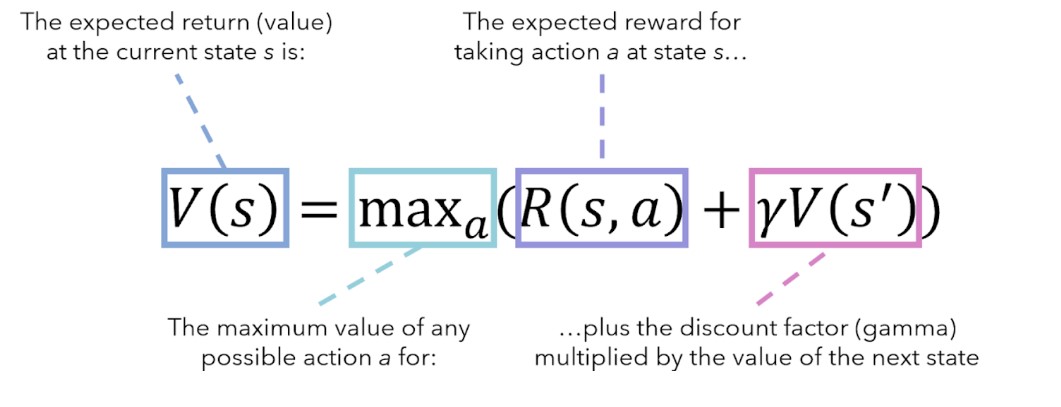
Bellman Equation Reinforcement Learning Example at Brent Peterson blog
NeurIPS Revisiting Bellman Errors for Offline Model Selection
[2402.02165] Towards Optimal Adversarial Robust Q-learning with Bellman ...
Analysis and Optimisation of Bellman Residual Errors with Neural ...
Revisiting Bellman Errors for Offline Model Selection
(PDF) Revisiting Bellman Errors for Offline Model Selection
(PDF) Analysis and Optimisation of Bellman Residual Errors with Neural ...
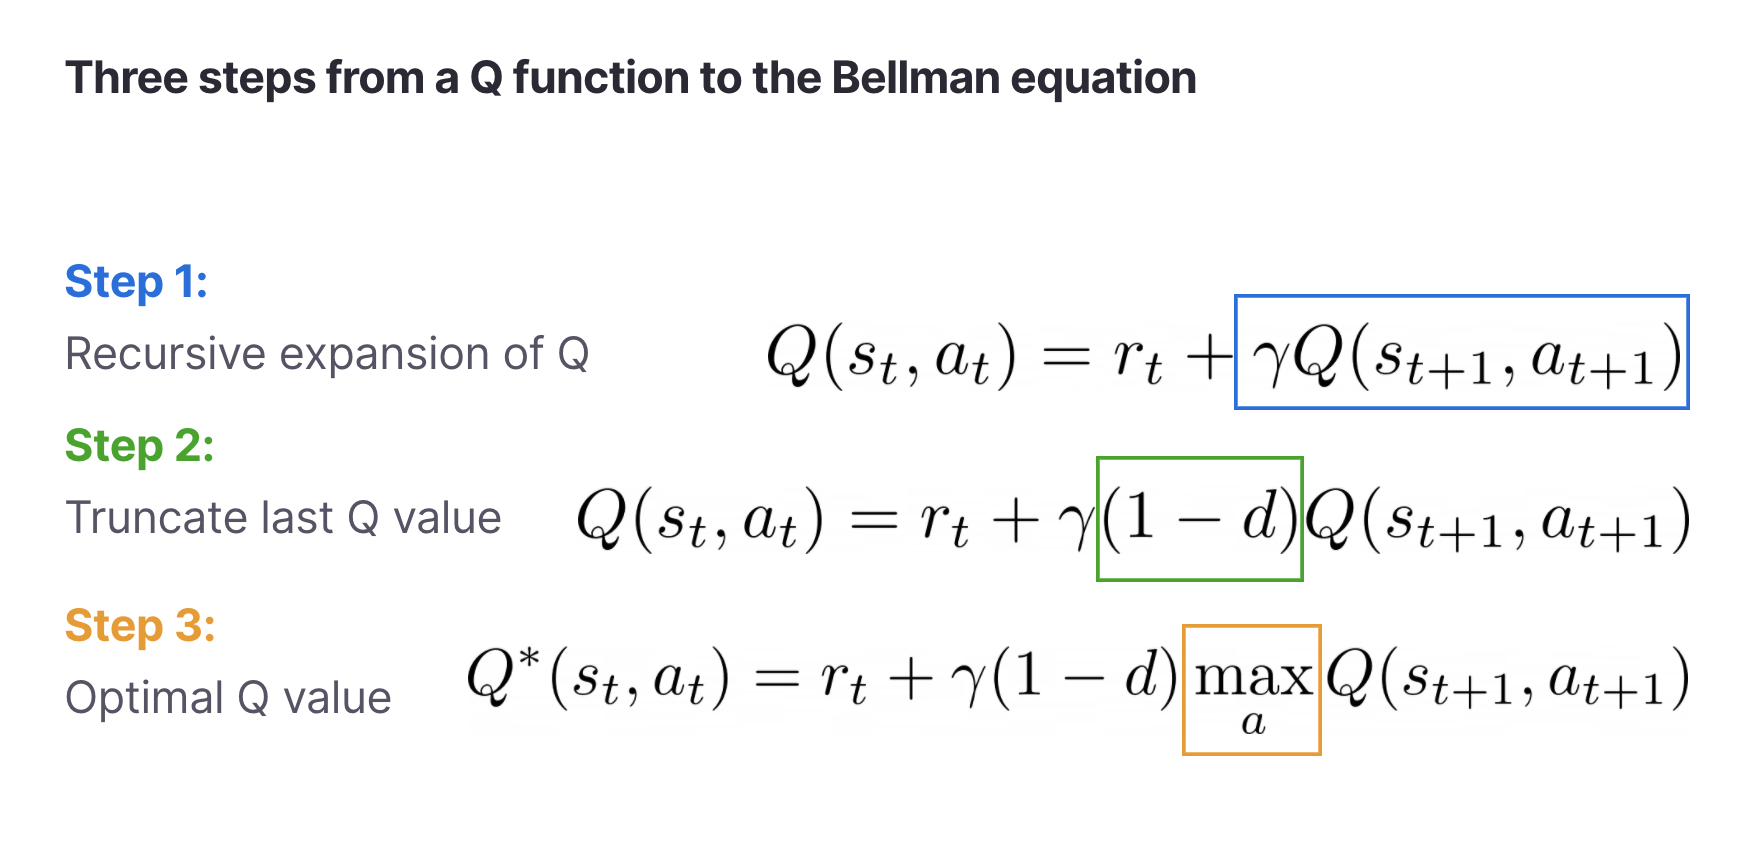
Bellman Equation in Reinforcement Learning
[2302.00141] Revisiting Bellman Errors for Offline Model Selection
Evaluating the quality of fixed-points for the projected Bellman errors ...
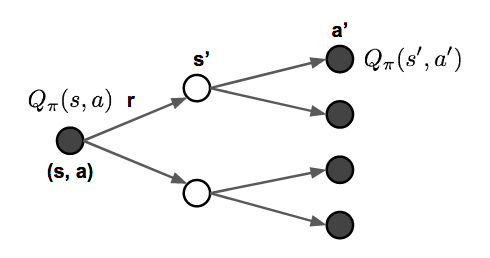
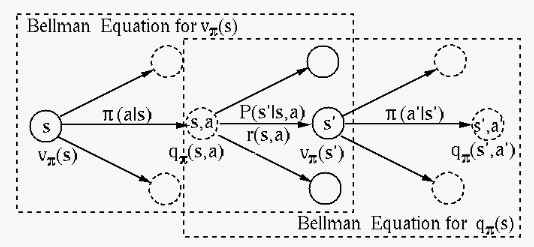
reinforcement learning - Missing steps in Bellman Equation and MDP ...
BEAR (Bootstrapping Error Accumulation Reduction)
Bellman Equations for Optimal Value Functions | GoGoGogo!
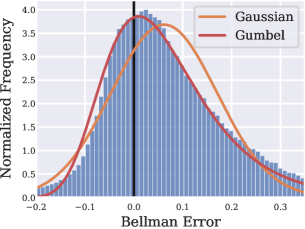
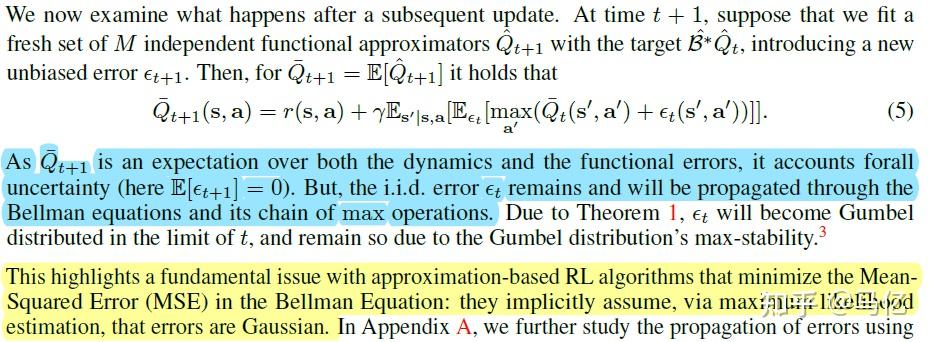
Exploration by distributional rl_bellman error 服从高斯分布-CSDN博客
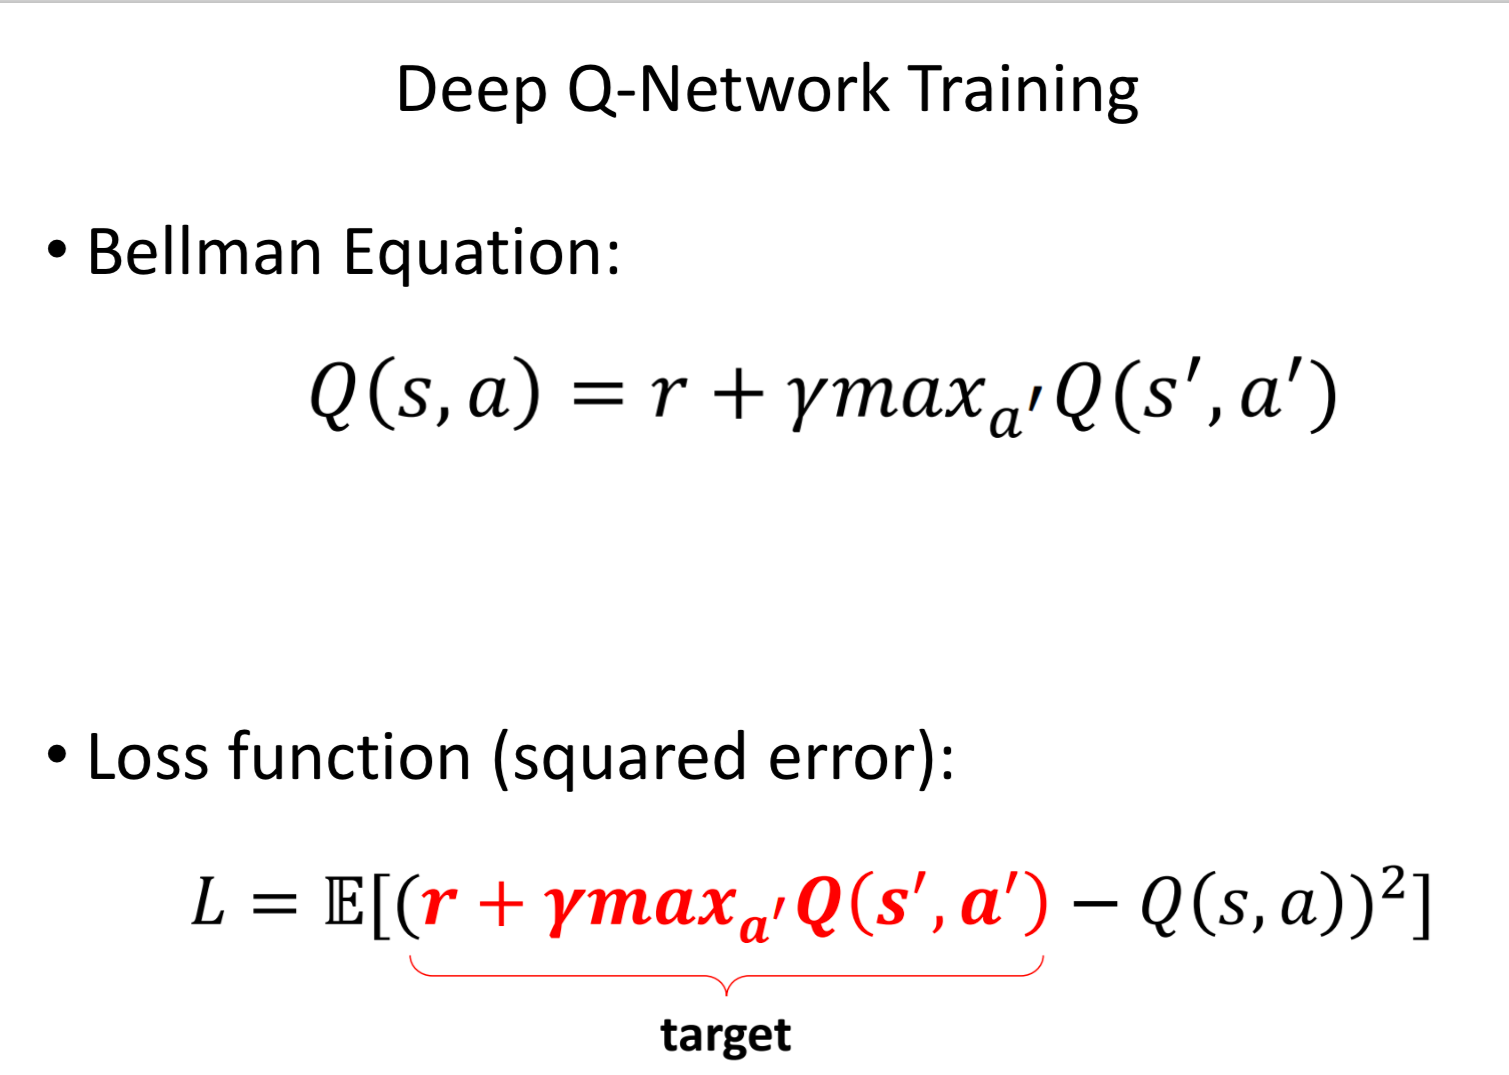
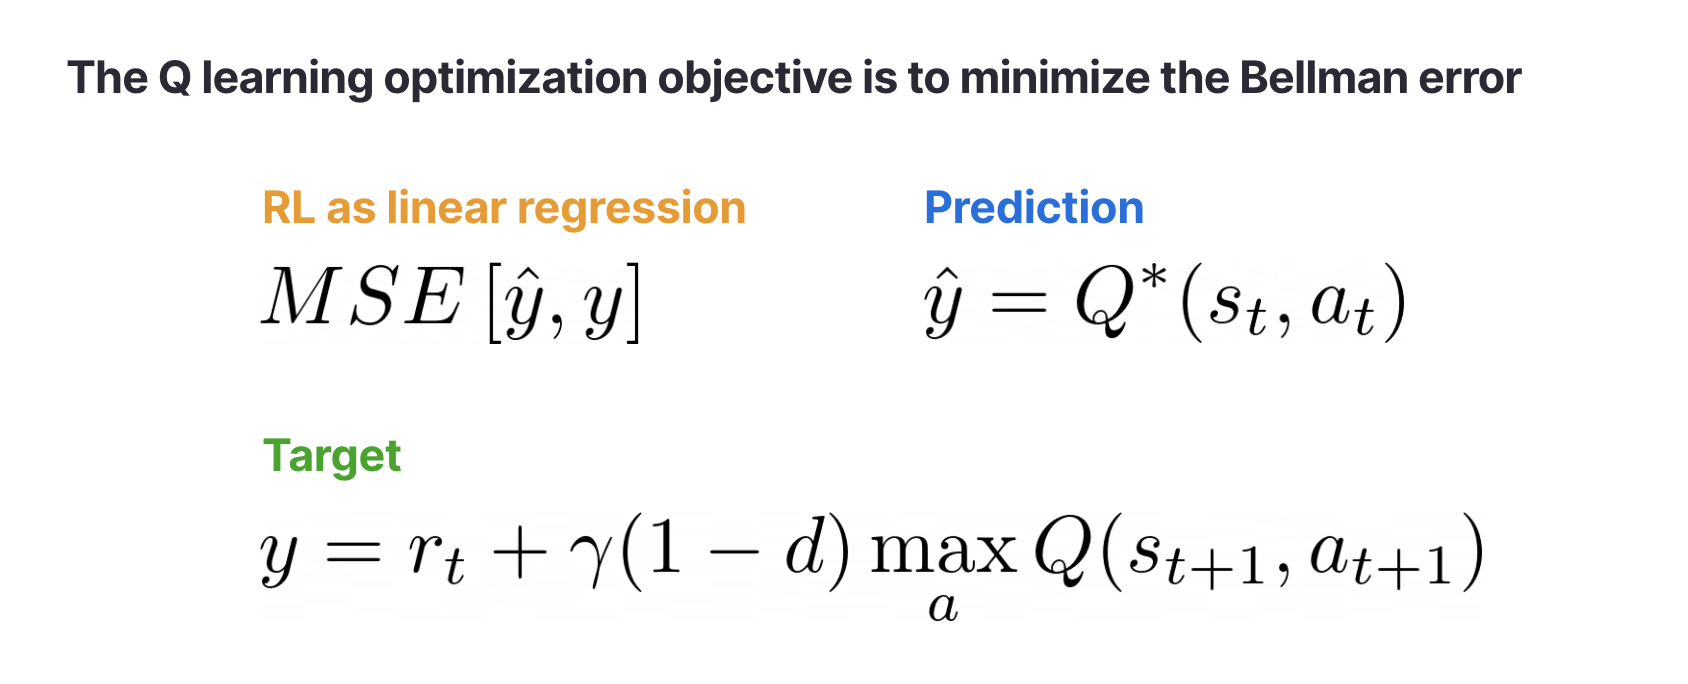
Reinforcement learning with Deep Q Networks | Anyscale
Sutton & Barto summary chap 11 - Off-policy methods for approximation ...
【万字专栏总结】离线强化学习(OfflineRL)总结(原理、数据集、算法、复杂性分析、超参数调优等)-腾讯云开发者社区-腾讯云
A value-based deep reinforcement learning model with human expertise in ...
动态规划寻找最优策略之Value Iteration(值迭代) - 知乎
[2301.02328] Extreme Q-Learning: MaxEnt RL without Entropy
Reinforcement Learning - Sutton (Book Notes)
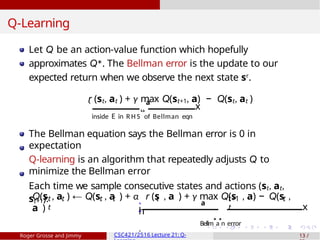
Lecture 21 ppt Q learning................ | PPTX
Bellman's equation Reinforcement learning - II | PPTX
Value Function Geometry and Gradient TD | PDF
[2501.02709] Horizon Generalization in Reinforcement Learning
Batch Reinforcement Learning | PPTX
[2505.11862] Q-Policy: Quantum-Enhanced Policy Evaluation for Scalable ...
Sutton & Barto, Ch. 11: Off-Policy Methods with Approximation (Personal ...
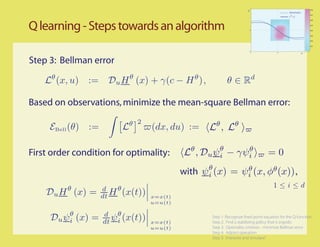
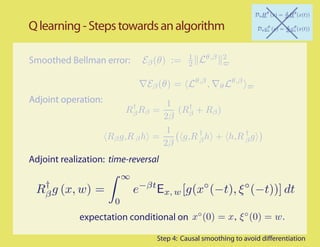
Q-Learning and Pontryagin's Minimum Principle | PDF
PPT - Reinforcement Learning Part 2 PowerPoint Presentation, free ...
Evolving Reinforcement Learning Algorithms
Geometric relationships between the square roots of the two ...
TD Learning with Exploration
论文速读——Extreme q-learning: Maxent RL without entropy - 知乎
PPT - Reinforcement Learning PowerPoint Presentation, free download ...
强化学习读书笔记(13)| Off-policy Methods with Approximation(下)-腾讯云开发者社区-腾讯云
MOBILE-Model-Bellman Inconsistency for Model-based Offline ...
Control block diagram of the loading process (right) and state ...
Figure 2 from Approximate Optimal Trajectory Tracking With Sparse ...
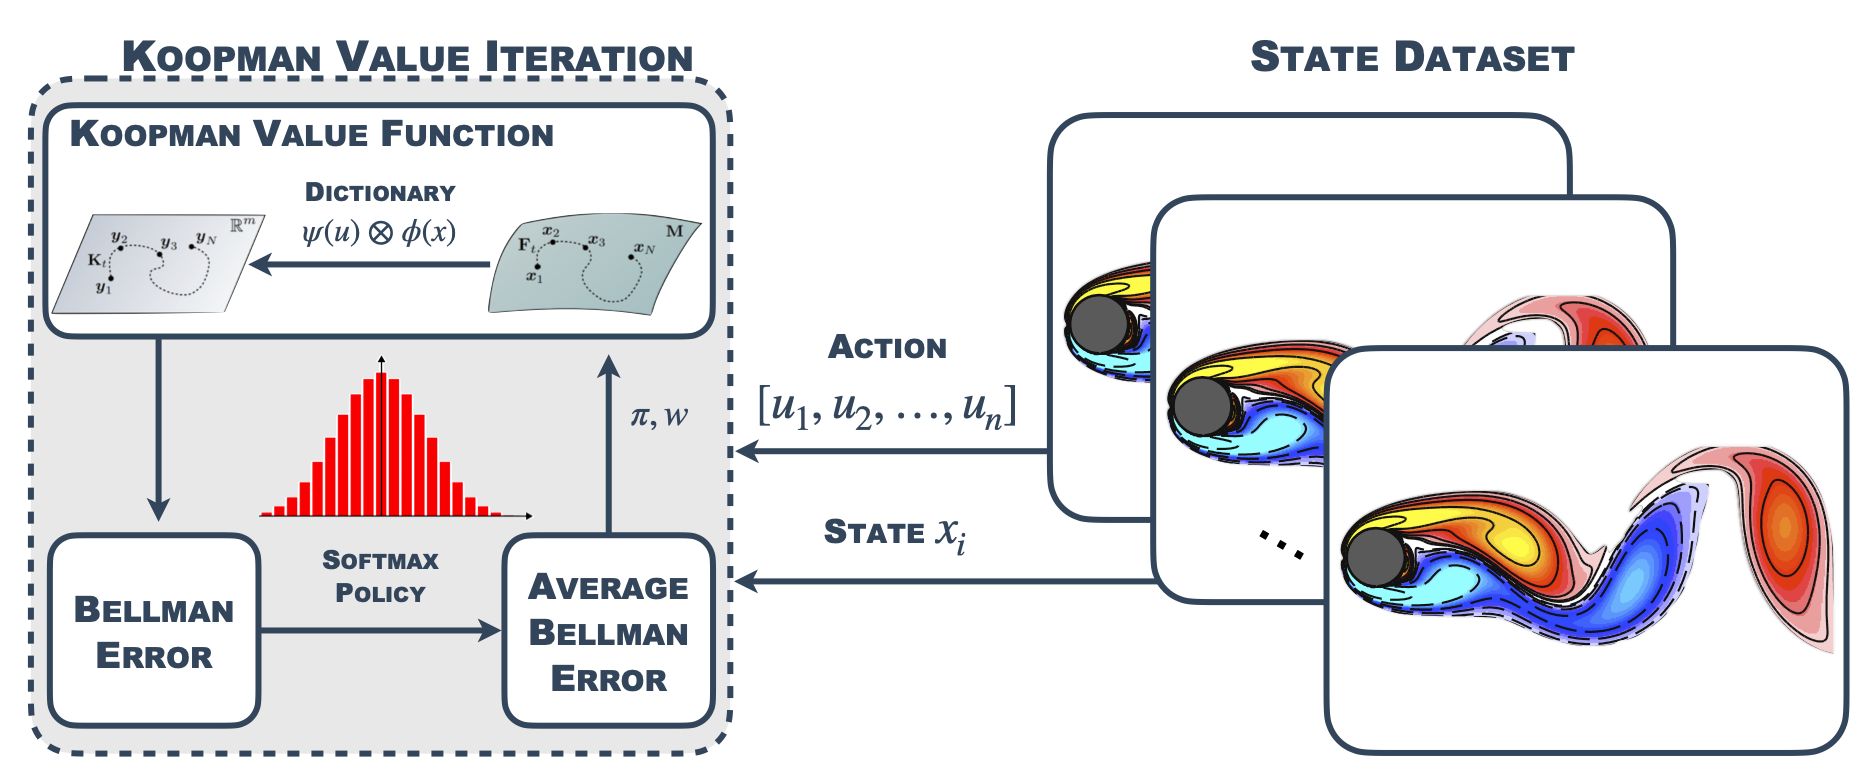
Koopman-Assisted Reinforcement Learning | Fusing Koopman operators with ...
Reinforcement Learning - DQN | PDF
How Agents Learn Through Trial and Error: Reinforcement Learning ...
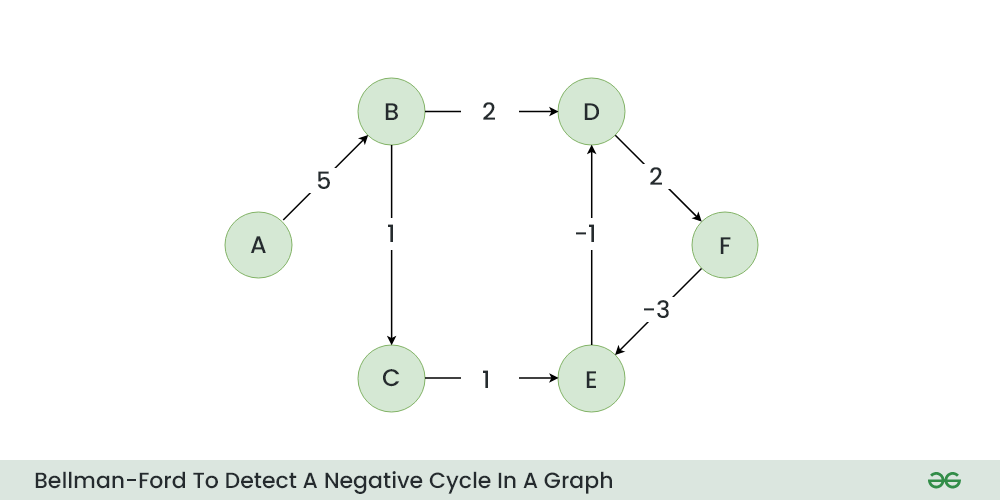
Bellman-Ford Algorithm Example In Computer Networks at Peter Price blog
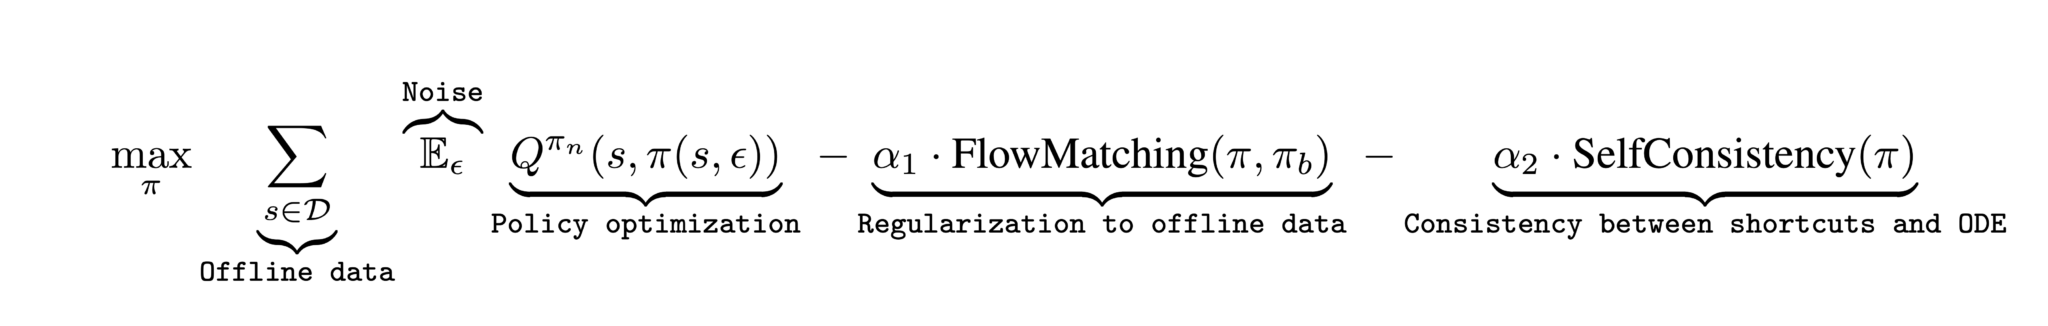
Scaling Offline Reinforcement Learning at Test Time - Kempner Institute
【论文笔记】BEAR: 通过减小Bootstrapping Error来进行离线RL学习 - 知乎
PPT - Lecture 14: Introduction to Reinforcement Learning PowerPoint ...
Average return over number of learning steps for hyperparameters chosen ...
Figure 1 from Automatic Induction of Bellman-Error Features for ...
《Extreme Q-Learning: MaxEnt RL without Entropy》论文阅读笔记 - 知乎
semi supervised Learning and Reinforcement learning (1).pptx
离线强化学习(Offline RL)系列3: (算法篇)策略约束- BEAR算法原理详解与实现 - 知乎
Value Iteration vs Q-Learning: Dynamic Programming Meets RL
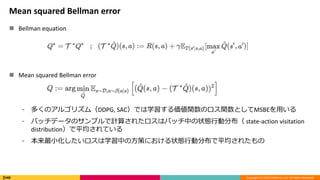
Fitted Q-iteration - グラフ機械学習と強化学習について
PPT - Reinforcement Learning : Dynamic Programming PowerPoint ...
GitHub - AiX-Lab-UWO/BETDQNet: Pytorch implementation of BETDQNet ...
A (Long) Peek into Reinforcement Learning | Yue'Log
[LG Aimers] 6. Reinforcement Learning
pages.hmc.edu - /ruye/MachineLearning/lectures/figures/